
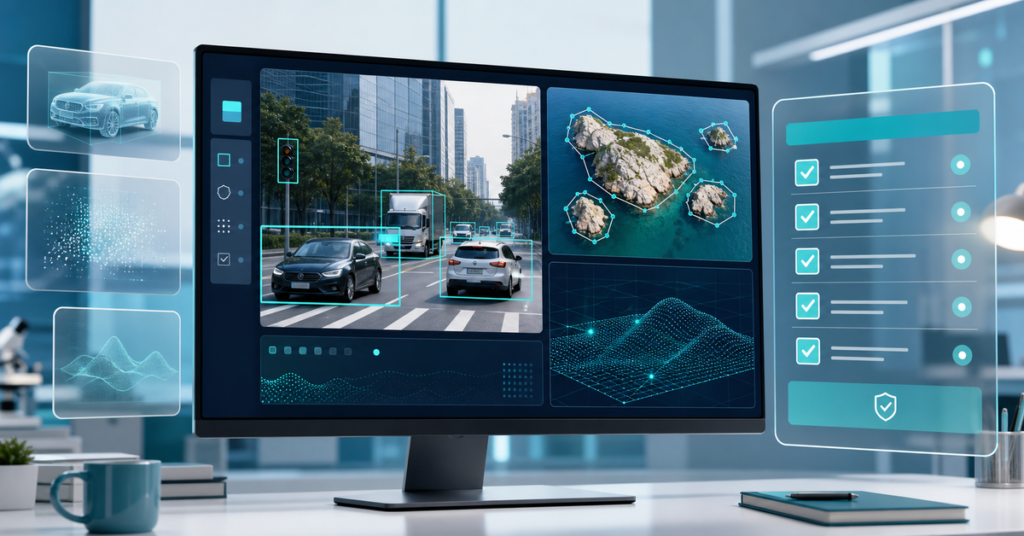
Why image annotation for computer vision affects model quality more than many buyers expect
Image annotation for computer vision is often discussed as a production task, but buyers should treat it as a model design decision. The annotation format determines what the model can learn, how reviewers measure quality, and how much rework appears after training begins. A dataset with the wrong geometry, weak class definitions, or inconsistent edge-case handling can look complete while still limiting model performance.
That is why teams should avoid choosing annotation types based only on price or tool familiarity. Bounding boxes, polygons, polylines, keypoints, and segmentation masks serve different model objectives. The right choice depends on whether the project is solving object detection, fine-grained segmentation, defect inspection, scene understanding, autonomous systems, retail shelf analysis, or another computer vision use case.
For procurement and operations teams, the practical goal is not to request the most detailed annotation possible. It is to request the level of precision the model actually needs, then design a QA workflow that keeps that precision consistent across large volumes. This is the same operating logic behind strong data annotation quality control and clear data annotation guidelines: format choice and workflow discipline have to support each other.
Start with the model objective before selecting an annotation type
A common mistake in image annotation for computer vision is to select the annotation format first and justify it later. The better sequence is to define the downstream model task, expected failure modes, and evaluation standard before choosing how images should be labeled.
If the project is training an object detector for inventory monitoring, traffic analysis, or general object presence, bounding boxes may be sufficient. If the model must understand exact object boundaries for medical imaging, defect detection, document layout segmentation, or advanced robotics, polygons or masks may be necessary. If the project depends on landmarks such as joints, facial features, or product handle positions, keypoints may matter more than either boxes or polygons.
This decision also affects cost and throughput. More detailed annotations require more time, more reviewer effort, and often more guideline complexity. Buyers should therefore ask not only what the model team wants, but what level of label detail will materially improve model outcomes. Extra precision that is never used in training can increase budget without increasing dataset value.
When bounding boxes are the right choice
Bounding boxes remain one of the most common formats in image annotation for computer vision because they are efficient, scalable, and often good enough for detection tasks. They work well when the model mainly needs to locate and classify an object within a reasonable area. Retail products on shelves, vehicles on roads, packages in warehouses, and people in surveillance or safety scenarios are typical examples.
Boxes are especially practical when object boundaries are visually fuzzy, when the downstream action only depends on approximate location, or when the dataset must scale quickly across large volumes. They are also easier to review than dense polygons because reviewers can compare class assignment, placement, and size with relatively fast checks.
However, boxes create real limitations. They include background pixels, overlap heavily in crowded scenes, and struggle with irregular shapes. For thin objects such as cables, tools, plant stems, or damaged edges, a box may capture too much irrelevant area. If the model must distinguish precise contours, a box can become a weak training signal rather than a simple shortcut.
When polygons or masks justify the extra effort
Polygons and segmentation masks are more demanding, but they are often the right investment when object shape matters. In image annotation for computer vision, they are useful for use cases where the boundary itself is part of the learning target: surface defects, medical structures, agricultural crop regions, map features, packaging damage, or industrial components with irregular outlines.
A polygon provides tighter geometry than a box, while a mask can represent the object at pixel level. That improves training data quality for segmentation models and can reduce the amount of background noise the model learns by accident. For teams measuring area coverage, shape change, overlap, or fine object separation, this extra detail is often necessary rather than optional.
The tradeoff is operational. Detailed annotations introduce more disagreement risk around edges, occlusion, reflections, shadows, transparent areas, and partially visible objects. If the instructions are weak, the dataset becomes expensive without becoming consistent. Buyers who choose detailed geometry should therefore plan for stricter calibration, slower throughput, and more sample-based quality checks from the start.
Attributes, occlusion rules, and class definitions matter as much as geometry
Many computer vision datasets fail because teams focus on the drawing tool and ignore the label logic around it. Image annotation for computer vision needs clear rules for class boundaries, occlusion, truncation, visibility thresholds, and difficult cases. Two annotators may draw similar boxes but still disagree on whether the object should be labeled, which class applies, or how to handle partial visibility.
A robust guideline should define when an object is too small to label, when motion blur makes an item unusable, how to handle overlapping objects, and whether reflected or printed objects count as real targets. It should also define attribute labels where relevant, such as damaged versus intact, open versus closed, occupied versus empty, or day versus night context.
This is where buyers should push vendors to show practical examples, not just promise tool expertise. If the provider cannot explain the operating rules for edge cases, the model team may later spend more time fixing dataset ambiguity than improving the model. The lesson is similar to multilingual projects such as multilingual text data collection for LLM evaluation: quality depends on realistic specification design, not on volume alone.
QA for image annotation for computer vision should be layered, not final-stage only
A final audit is not enough for large-scale image annotation for computer vision. By the time a final review catches a repeated error pattern, thousands of labels may already need correction. A stronger workflow uses layered QA: pilot sets, reviewer calibration, random sampling, targeted sampling, and issue-driven feedback loops.
Pilot batches should test both the annotation geometry and the written instructions. Reviewer calibration should compare how different reviewers interpret the same ambiguous images. Random sampling helps estimate overall quality, while targeted sampling focuses on small objects, crowded scenes, new classes, or low-performing annotator groups.
Useful QA metrics go beyond pass or fail. Buyers should ask about class confusion rates, reviewer override rates, missing-object frequency, box tightness or mask-boundary error patterns, and turnaround differences by class type. When these metrics are tied back to examples and guideline updates, the workflow becomes measurable instead of subjective.
Questions buyers should ask before approving a computer vision annotation vendor
Before starting a project, buyers should ask operational questions that reveal whether the vendor can control consistency at scale.
- Which annotation type is recommended for the exact model objective, and why?
- How are class definitions, occlusion rules, and minimum-size thresholds documented?
- What pilot process is used to refine the guideline before full production?
- How are polygon or mask edge disagreements reviewed and resolved?
- Which QA metrics are tracked besides overall accuracy?
- How are difficult images escalated, and how are rule updates communicated to active annotators?
- What proportion of work is rechecked by reviewers, and how does that change for high-risk classes?
These questions matter because image annotation for computer vision is not only a labor-scaling task. It is a controlled data production system. Vendors that can explain this clearly are usually better positioned to support stable model development.
How Smart Language Service supports image annotation for computer vision
Smart Language Service supports image annotation for computer vision projects with practical workflow design, multilingual operations support, reviewer calibration, and measurable QA. We help teams choose the right annotation level for the model objective, prepare clear instructions, manage edge cases, and maintain quality across large annotation volumes.
For buyers building datasets for detection, segmentation, inspection, retail, robotics, and other vision use cases, the key decision is not whether annotation can be completed. It is whether the dataset will remain consistent enough to support real model improvement. When annotation type, guideline quality, and QA design are aligned from the beginning, image annotation becomes a model asset rather than a rework source.